 BioLLM
peptide research index · robinhood chain
The body is the runtime.
Peptide discovery is a language problem. Amino acids are tokens, a sequence is a sentence, and something already knows how to read them.
the model reads biology, writes peptides.
Robinhood Chain block — · chain 4663 · CA 0x67C61Bfb169ce68A61EF28E4CE9D7f53EFBd1e18
vitals · live from the chain
refreshes every 30s
That is the entire tokenized LLY float, backing a company worth hundreds of billions. $biohacking pairs against it. Unlaunched numbers read “not characterised” — same as the index.
sources: rpc · dexscreener
Type what hurts.
Plain language in. Ranked peptides out, each one citing the study it came from. No account, no server — it runs in your browser.
It launches against a stock.
$biohacking pairs against LLY — tokenized Eli Lilly stock — on long.xyz. No stablecoin pool. The index catalogues the molecules; the pair is the company that makes them.
pair asset LLY 0x8005d266423c7ea827372c9c864491e5786600ea · verify the address in Robinhood's own registry ↗
The meme is the mechanism.
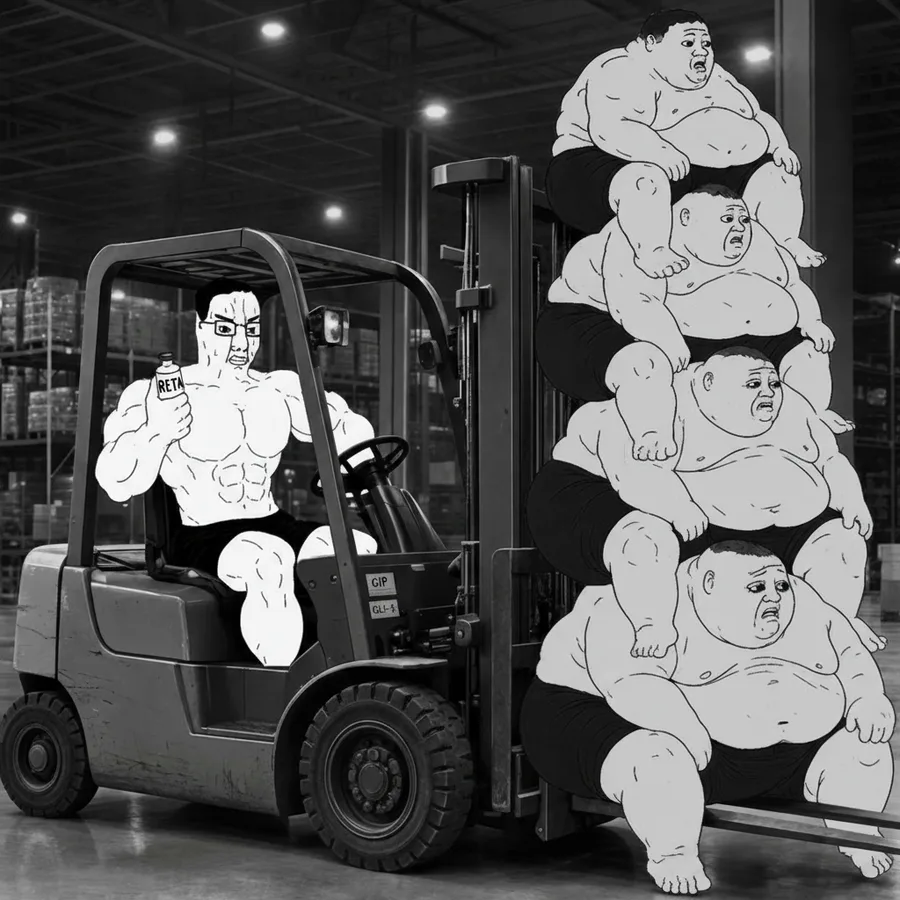
Retatrutide hauls three fat jaks because it hits three receptors. All 33 →
Real molecules. Real coordinates.
Drawn from PubChem's computed coordinates — the geometry chemistry software uses. The whole wall →
Scale
The index runs from two-residue dipeptides to insulin. Bars are heavy-atom counts, to scale.
Check it yourself
Sourced
761 citations. 79 PubChem records. 57 with trials.
Self-checked
20 sequences mass-verified to 1.5 Da. Disagreements are printed, not hidden.
Honest
Unknown fields read not characterised. The gaps are why the rest counts.
The model writes new ones.
It reads the corpus and writes sequences that aren't in it. Every one is screened before it ships — the method is public. What survives goes to the registry: hashed, timestamped, open.